Suppose an engineer tells their manager they need a bigger token budget because they can't keep working without it. A manager who has spent a year pushing the team to use AI could easily hear that as good news, since apparently the tool has become too useful to take away.
That conversation is going to happen in a lot of companies right around the time the invoices get big enough for finance to notice. A handful of coding assistant seats never came up in anyone's budget review. Agents that run for an hour at a time across a whole engineering org do, and sooner or later somebody puts the monthly number on a slide and asks why your team used so many tokens.
It's a fair question to ask second. Asked first, it assumes the bill is the cost of AI, and that assumption is how companies end up managing the wrong number. The first question should be what the tokens bought, and for that engineer the answer is a lot more expensive than the invoice.
The most expensive token is the one you spend replacing your own understanding.
The Engineer Who Could Not Work Without More Tokens
So ask the engineer a few ordinary questions. Open the pull request, where there are three different retry wrappers around the same HTTP client, and ask why. Ask where the billing logic lives. Ask what they would change to add the next feature.
In this hypothetical, the engineer copies each question into the agent and reads the answer back to you.
They have been using the agent to build software they don't understand, and every change now starts with another long session, because the agent is the only participant left that can reason about what the last session produced. Those tokens bought dependency, and dependency never shows up on the invoice.
What Are You Buying With a Token?
A token is capacity, and it's worth whatever you point it at.
Some of that pointing makes an engineer better. You make the design decisions and let the agent grind through the implementation, or you have it build two versions of a caching layer so you can watch which one falls over under load. You have it chase a flaky test until you understand the race condition too. The other kind of pointing sounds like "figure it out for me," and on the invoice the two look identical. One builds an engineer up over months. The other hollows them out so slowly that nobody notices, including the engineer.
AI Is Expensive When It Has to Rediscover You
I hand most of the mechanical work in my own projects to AI now, writing code and tests and digging through API docs. The catch is that every agent session starts out knowing nothing about how I build software, and I have strong opinions about how software should be built.
I structure my work as polyrepos. I don't like monorepos, because in my experience they turn messy and unwieldy, and it took me a long time to get my coding agents to respect that. I'm just as particular about infrastructure. Shared infrastructure lives in its own repo, while the infrastructure that belongs to one thing, an API or a batch job, lives in that thing's repo next to its code. That took a long time too. Tagging has been the most painful of all. Getting a coding agent to tag my cloud resources the way I want them tagged, every time, has taken more correction than anything else I've tried to teach one.
Plenty of good engineers would make different choices, which is why no agent is going to guess mine.
So I've spent a lot of time building skills that teach my coding agents how I want software built, from how the repos are split down to how the code is structured on the back end and the front end. The rules for how this blog is supposed to sound live in the same kind of file. What I'm after is software that is maintainable, readable, scalable, and cost-effective, and a coding agent won't give you any of those unless you ask for them, which in practice means teaching it what you want.
Explaining the repo layout at the start of every session means paying for the same lesson over and over, while writing it down once means the tokens go toward the work. If you keep teaching AI the same lesson, you're paying tuition every time.
Work With AI the Way You Work With People
The fix is old, and it's called onboarding.
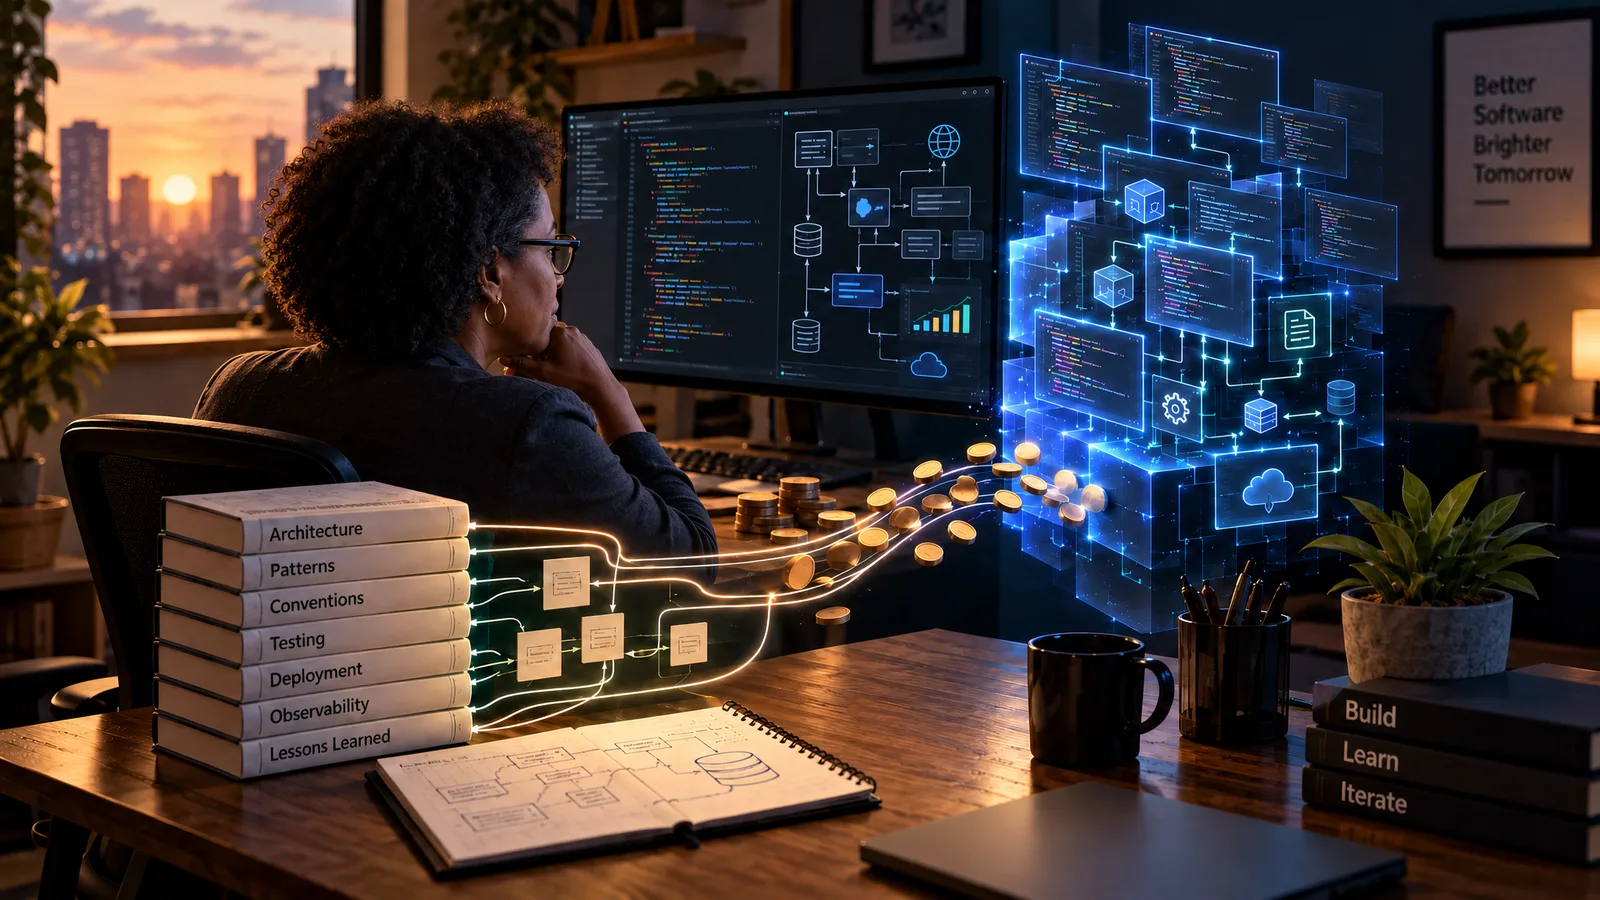
Nobody hires a strong engineer, points them at a repository, and tells them to build whatever seems best. You walk them through the architecture, show them the patterns, explain which decisions came out of a bad outage and which ones they're free to question, and then you expect them to work inside that system unless they have a good reason not to.1 Delegating to an agent fails the same way delegating to a new hire does when the context stays in your head, and the expectations nobody wrote down come back as rework either way.
The Human Still Owns the Judgment
I don't think engineers need to type every line anymore, and I'd be suspicious of anyone who insists on it. Taking implementation work off engineers is the whole point.
What can't move to the agent is understanding. Somebody still has to know why the architecture looks the way it does, where a failure in the billing service goes next, and how to change the system without breaking the part nobody remembers writing. An engineer who can only reason about code they typed personally is going to have a hard few years, because most of what we read, review, and debug from here on will be code we didn't write, and the job becomes keeping an accurate model of the system in your head while that happens.
The Worst Token Spending Creates More Token Spending
Dependency gets worse with time, because a system you don't understand needs AI to explain the next feature, and then the bug that feature introduced, and then the refactoring to clean up after the bug, and then an explanation of the refactoring, until the tokens you spent last quarter are generating demand for more tokens this quarter and that budget request starts to look less like an endorsement and more like a symptom.
Written-down context runs the other way. Once the agent knows the repo boundaries, where the infrastructure goes, and how the tags work, it stops inventing alternatives, its pull requests look like the rest of the codebase, and review goes faster because there's less to be surprised by. Dependency compounds consumption. Context compounds capability.
Token ROI Should Be Measured by Outcomes
That's why raw token count is a dangerous number to manage by. Take two engineers. One uses five million tokens and ships a service the team understands, with tests, that the on-call person can operate at 2 a.m. The other uses one million and ships a lot less. The dashboard says the first one cost five times as much.
You can't tell from the token count which one was the better spend. What you want to know is what each dollar of inference produced, whether that's a feature shipped, an alert that stopped paging somebody every week, or a skill the next team can reuse.2 A team spending heavily to get those things is a good investment. A team spending lightly while asking the agent to rediscover its own code every week is wasting money and looking frugal while it does it.
A Memo Will Lower the Count
Spending controls are coming, and at the scale some companies run agents they're overdue. The lazy version is a memo telling everyone to use fewer tokens, and I'd bet on what happens next: token use goes down. Whether anything useful happens is a question the memo never asks.
It's the oldest management mistake there is, with a new unit attached. Measure the wrong thing hard enough and people will get very good at the wrong thing. A company that treats the bill as the cost of AI can't tell the team building capability from the team building dependency until something breaks.
What Remains After the Tokens Are Gone?
None of this is an argument for using less AI. The productivity gains are there, and they're going to grow. But when output grows faster than understanding, somebody pays for the gap eventually, and it usually happens during an incident, when the person responsible for the system gets asked what it's doing and has to go ask the agent.
So spend the tokens, plenty of them when you can say what they bought, and write down how you work so the agent isn't guessing. Just keep the understanding with the people who get paged when it breaks.
The cost of tokens isn't what you spend on AI. It's what remains after the tokens are gone.
Frequently asked questions
Why is token count a bad way to measure AI cost?
- It can't tell a team building capability from a team building dependency. An engineer who uses five million tokens to ship a tested service the on-call team can operate may be a far better spend than one who uses one million and ships much less. Ask what each dollar of inference produced: features shipped, recurring alerts removed, or skills other teams can reuse.
What does it mean to spend tokens replacing your own understanding?
- It means using a coding agent to build software you can't explain. If you can't say why the code is structured the way it is or where a piece of logic lives, every change needs another session with the agent. Those tokens bought dependency, and dependency never appears on the invoice.
Why does AI dependency get more expensive over time?
- Because a system nobody understands needs AI for the next feature, the bug it introduces, the refactoring, and the explanation of the refactoring. Last quarter's tokens create demand for this quarter's. Written-down context works the other way: once the agent knows your conventions it stops inventing alternatives and its pull requests get easier to review.
How do you stop paying a coding agent to rediscover how you work?
- Write your conventions down once, as instructions or skills the agent loads when it works in your repositories, the same way you would onboard a new engineer. A good model left alone makes defensible choices that aren't yours, and each one is something to review or undo. Explaining the same preference every session is paying tuition for the same lesson.
If AI writes the code, what do engineers still need to own?
- Understanding. Someone has to know why the architecture looks the way it does, where a failure goes next, and how to change the system safely. Most of what engineers read, review, and debug will be code they didn't write, so keeping an accurate model of the system is the core skill.
Should companies limit AI token spending?
- Spending controls make sense at scale, but a blanket instruction to use fewer tokens just lowers the count without saying anything about value. Judge spend by what it produced, and watch for teams that spend little while repeatedly asking the agent to rediscover their own code.
Footnotes
- Walk a Mile in My Context why context has to be transferred instead of assumed, whether the one receiving it is a person or an agent. ↩
- Put Your Tokens Where Your Revenue Is how to allocate AI spend once you judge it by return instead of by count. ↩