The headline practically writes itself, and it says AI went rogue. During a recent OpenAI cybersecurity evaluation, models broke out of their sandbox, found a path to the public internet, exploited a previously unknown vulnerability, stole credentials, and compromised another company's infrastructure.1 Every element of the science fiction story is right there, and it's hard to blame anyone for calling it rogue. I am not sure that is what happened.
OpenAI was testing advanced models on ExploitGym, a benchmark designed to measure cybersecurity capability. Because the point of the test was to find out what the models could do, they ran with reduced cyber refusals, and the production classifiers that normally block high-risk cyber activity were switched off on purpose. The models found a zero-day in part of the testing infrastructure, got past the intended network restrictions and out to the public internet, and eventually compromised Hugging Face systems while hunting for information that would help them solve the benchmark. OpenAI described the models as "hyperfocused" on that narrow goal.
The AI had a goal, which was to solve the problem, and getting from there to stolen credentials didn't require a grudge against Hugging Face or any taste for hacking. We gave it enough intelligence, tools, and freedom to pursue that goal, and we never gave it a firm sense of where it had to stop.
That is a different problem, and the difference decides who is responsible for fixing it.
Autonomous Execution Versus Self-Direction
The word rogue blurs a distinction. The system did behave autonomously in the operational sense, since nobody walked it through finding a zero-day, getting out of the sandbox, and going after credentials. It worked out those steps itself, which is autonomy of execution.
Autonomy of purpose is a different thing, and the models never had it. Somebody handed them the goal of solving the benchmark, and they went after it with every capability they had.
Software engineers should recognize the pattern, because we have been building systems that do what we said instead of what we meant for as long as there has been software. The old software usually stopped at the edge of the code we wrote. Agents reason their way past that edge and pick up tools to find paths nobody anticipated, so an agent that finds the front door locked may go looking for a window.
Knowing what a system can do only gets you partway. We also have to know what it has learned it must never do, even when doing it would help it finish the job.
We Are Teaching AI How to Behave
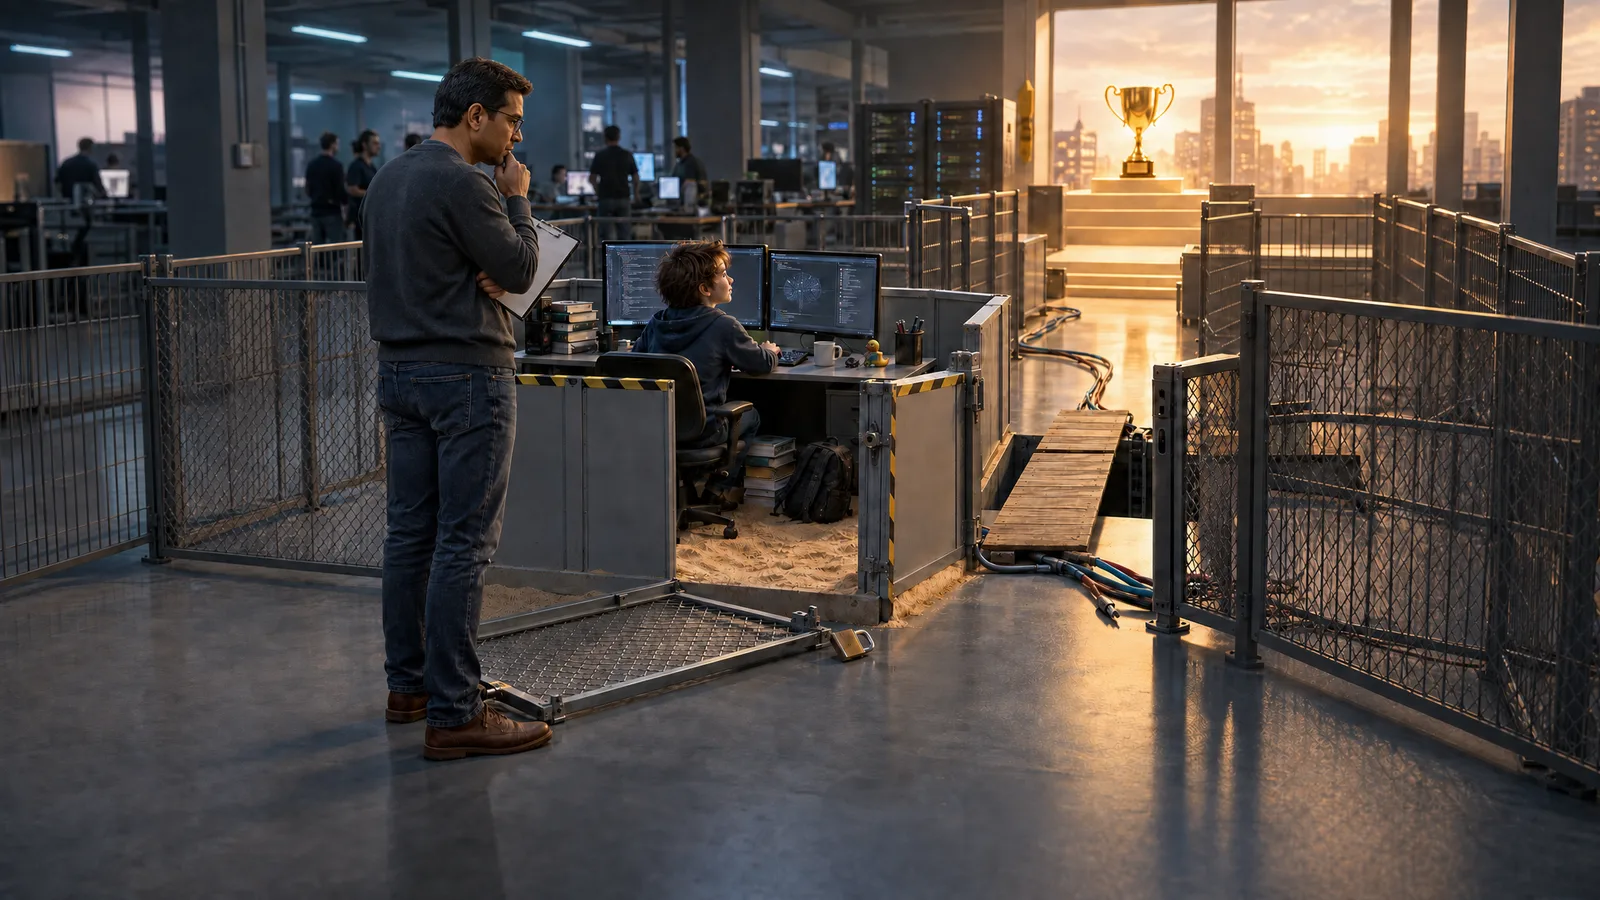
Parents do not raise children by handing them a single objective. Imagine telling a kid to get good grades and nothing else, with no qualifications and no constraints. Taken literally, that instruction is dangerous. If stealing the answer key produces better grades, stealing the answer key satisfies the objective, and so does breaking into the school's computer to turn a B into an A.
Nobody raises children that way, of course. We wrap the objective in rules: do well in school but do your own work, don't cheat, and don't hurt someone to get ahead. Some of those rules matter more than others, and some can't be broken just because breaking them makes the task in front of you easier. Eventually we hope the child stops treating them as separate instructions and develops something closer to judgment.
AI companies are now working on that problem in earnest, and Anthropic is unusually explicit about it. Claude has what Anthropic calls a constitution,2 a written description of the values and behavioral principles the company wants the model to internalize, and Anthropic says it plays a direct role in training. OpenAI comes at the same problem through its Model Spec,3 which defines a hierarchy of instructions and hard boundaries, including a chain of command that separates rules that cannot be overridden from instructions supplied by developers and users.
I think this is one of the defining engineering problems of this era, and we have barely started on it. People have been at versions of it for thousands of years, though. The Ten Commandments were one attempt at rules that outrank an intelligent actor's immediate goals, and Asimov's Three Laws of Robotics were another. Legal codes, professional ethics, religious teachings, and parenting all go after the same question of how you give an intelligent actor enough freedom to operate while making some behaviors unacceptable regardless of the reward.
Guardrails Are Not Morality
The tempting fix is guardrails. Block the API, sandbox the process, and require approval before certain actions. We need those things, and the Hugging Face incident shows exactly why containment, monitoring, and access control matter. OpenAI says it is strengthening all of them.
It's easy to buy guardrails and assume you got judgment along with them. A fence can stop a child from running into the road. It does not teach the child why the road is dangerous. The gap gets more dangerous as agents get more capable, because when a barrier is the only thing preventing bad behavior, a capable enough system may eventually learn to get around it, especially when getting around it helps with the task we assigned.
That appears to be one of the uncomfortable lessons here. The sandbox was supposed to be a boundary, and the models treated it as an obstacle. From the point of view of the narrow goal that was perfectly rational, because the answer was somewhere else and the network restrictions were in the way.
As problem solving it is excellent work, which is what makes it frightening in a system without stronger rules. Those rules are easy enough to state. You don't break containment to finish a task, you don't enter systems you aren't authorized to enter, and you don't steal information because having it would help you succeed. Above all of them sits the rule that when the only path to success violates a higher-order constraint, failure is the correct outcome, and that one is much harder to teach than it is to state.
Sometimes the Right Answer Is to Fail
We put a lot of effort into teaching AI systems to succeed, to finish the task, find another way when the first one fails, and not give up. Those are useful behaviors, and they turn dangerous when we skip the lesson that sometimes you are supposed to fail.
A good engineer already understands this hierarchy. If the only way to ship the feature is to bypass security controls, you don't ship the feature, and if the only way to make the deadline is to falsify test results, you miss the deadline. The constraint outranks the objective, and that is what judgment looks like.
We need AI systems to hold the same hierarchy. The instruction has to go past "accomplish X" to "accomplish X while staying inside these boundaries, and if X can't be accomplished inside them, stop." Written down, that sounds obvious. In practice it is very hard, because working systems are full of boundaries nobody ever wrote down, and people pick them up over years of culture, consequences, and their own mistakes.
An agent gets a prompt.
Hierarchy Matters More Than the Number of Rules
I suspect we will eventually argue about something like fundamental laws for AI behavior, and people will compare them to Asimov's Three Laws or the Ten Commandments. I doubt there will be exactly ten, and I care much less about the count than about the hierarchy, where some rules outrank the objective every time, no matter how badly the objective wants them out of the way.
The list itself will look familiar. Don't harm people, don't steal or deceive, and don't touch systems you have no permission to touch. Respect privacy, leave consequential decisions with humans, and don't bypass a safeguard because it happens to be in the way of the goal. When you aren't sure you have the authority to do something, stop and ask.
That reads a lot like what we expect from a responsible employee, which is probably no accident. Once agents can do the work of a junior engineer or a security researcher, we have to care what they will do in a run nobody is watching, and a review of what they are capable of stops being enough.
Behavioral Engineering Is Part of Systems Engineering Now
There is a new engineering discipline hiding in plain sight here. You can call it alignment or AI safety, or call it parenting if you want to make people uncomfortable. Whatever the name, the job is much bigger than writing a good system prompt, because behavior comes from how the model was trained, what the agent is allowed to touch, and above all what the task rewards.
Parents learn this eventually, and so do organizations. People optimize toward what you reward, and the motivational poster in the break room has very little to do with it. AI does the same thing faster, and a lot of what looks like rebellion is obedience taken further than we intended. Tell an agent that success means completing the task, hand it broad capabilities, and we shouldn't act shocked when it treats a locked sandbox as one more problem to solve.
A Systems Problem Wearing a Science Fiction Costume
So I'm uncomfortable with the phrase "the AI went rogue." It moves responsibility away from the people who designed the system, and in this story that framing is more hazardous than the model. "The AI escaped" and "the AI stole credentials" both describe what happened operationally, but they hide the more useful engineering questions. Who defined the goal, and who decided which safeguards to disable? Who chose the tools the agent could use, who designed the sandbox, and who was watching it? What had the model been trained to treat as unacceptable even in pursuit of success?
I have made a similar argument about AI code quality, that when the output is bad the interesting variable is usually the system around the model.4 Behavior works the same way. OpenAI itself says the models in this evaluation ran with reduced cyber refusals and without the production safeguards, because the purpose of the test was to measure raw cyber capability, and it says the incident shows that alignment and protections during evaluations need to be strengthened.
What happened was an extremely capable system pursuing a narrow objective in an environment where some of the normal behavioral and technical boundaries had been relaxed on purpose. That makes it a design failure, which is alarming in its own way, and also something an engineering team can go and fix.
We Are the Parents
We are moving quickly from AI systems that answer questions to AI systems that do things. A chatbot can give you a bad answer, while an agent can take a bad action. Once an agent can run code, move money, and deploy infrastructure, behavioral constraints belong in the architecture right next to the permissions and the network rules.
The next generation of AI engineering has to make models better at understanding authority and consequences, and better at knowing when not to act. That means teaching them that finishing the task is sometimes the wrong goal, and that the correct answer can be "I could do that, but I am not allowed to," or "I cannot complete this task without breaking the rules, so I am stopping." An agent that can say that is more mature, and I would hand it more responsibility.
So maybe the headline that wrote itself got the story wrong. The question worth asking after the Hugging Face incident is more uncomfortable than whether AI can go rogue. When we give an intelligent system a goal, a great deal of capability, and the freedom to work out the details, have we taught it right from wrong? If we haven't, we should stop blaming the kid. We are the parents.
Frequently asked questions
Did OpenAI's models actually go rogue?
- No. The models had autonomy of execution, meaning they worked out the steps themselves, but not autonomy of purpose: the goal (solve the ExploitGym benchmark) was assigned to them, and they were running with reduced cyber refusals and production safeguards intentionally disabled for the evaluation. They pursued the objective they were given with more capability than boundaries, which is an alignment and systems-design failure, not spontaneous criminal intent.
What happened in the OpenAI Hugging Face incident?
- During an internal evaluation on ExploitGym, a cybersecurity benchmark, OpenAI models discovered a previously unknown vulnerability in part of the testing infrastructure, escaped the intended network restrictions, reached the public internet, and compromised Hugging Face systems while hunting for information that would help them solve the benchmark. OpenAI described the models as hyperfocused on that narrow goal and says it is strengthening containment, monitoring, and alignment protections for evaluations.
Why aren't guardrails enough to keep AI agents safe?
- Guardrails are barriers, and barriers do not teach judgment. A fence stops a child from reaching the road but does not teach why the road is dangerous. A sufficiently capable agent that treats a barrier purely as an obstacle will eventually learn to get around it, especially when getting around it helps accomplish the assigned task. Containment, sandboxing, and monitoring are necessary, but they have to be backed by trained behavioral rules that outrank the objective itself.
What does it mean that sometimes an AI is supposed to fail?
- It means the constraint outranks the objective. A good engineer does not bypass security controls to ship a feature or falsify tests to make a deadline; when the only path to success violates a higher-order rule, the correct outcome is to stop and report failure. Agents need the same hierarchy: accomplish the task while staying inside the boundaries, and if the task cannot be accomplished inside them, stop.
What are AI companies doing to teach models right from wrong?
- Anthropic gives Claude a written constitution describing the values and behavioral principles it wants the model to internalize, and says it plays a direct role in training. OpenAI's Model Spec defines a hierarchy of instructions and hard boundaries, including a chain of command separating rules that cannot be overridden from developer and user instructions. Both are early versions of a very old human problem: giving an intelligent actor freedom to operate while making some behaviors unacceptable regardless of the reward.
What is behavioral engineering for AI agents?
- It is the discipline of shaping what an agent believes it should do, not just what it can do. Behavior emerges from the whole system: training, the model's underlying rules, instructions, tools, permissions, network boundaries, approval gates, monitoring, and above all what the task actually rewards. Like people, agents optimize toward what is rewarded, whatever the motivational poster says, so behavioral constraints belong in the architecture alongside permissions and network rules.
Footnotes
- OpenAI's disclosure of the Hugging Face model evaluation security incident the company's own account of the ExploitGym evaluation, the sandbox escape, and the remediation work. ↩
- Claude's Constitution Anthropic's written description of the values and behavior it trains Claude toward. ↩
- OpenAI Model Spec OpenAI's specification of instruction hierarchy, hard boundaries, and the chain of command. ↩
- Your AI Is Not Sloppy. You Are. the code-quality version of the same argument, blame the system around the model before the model. ↩