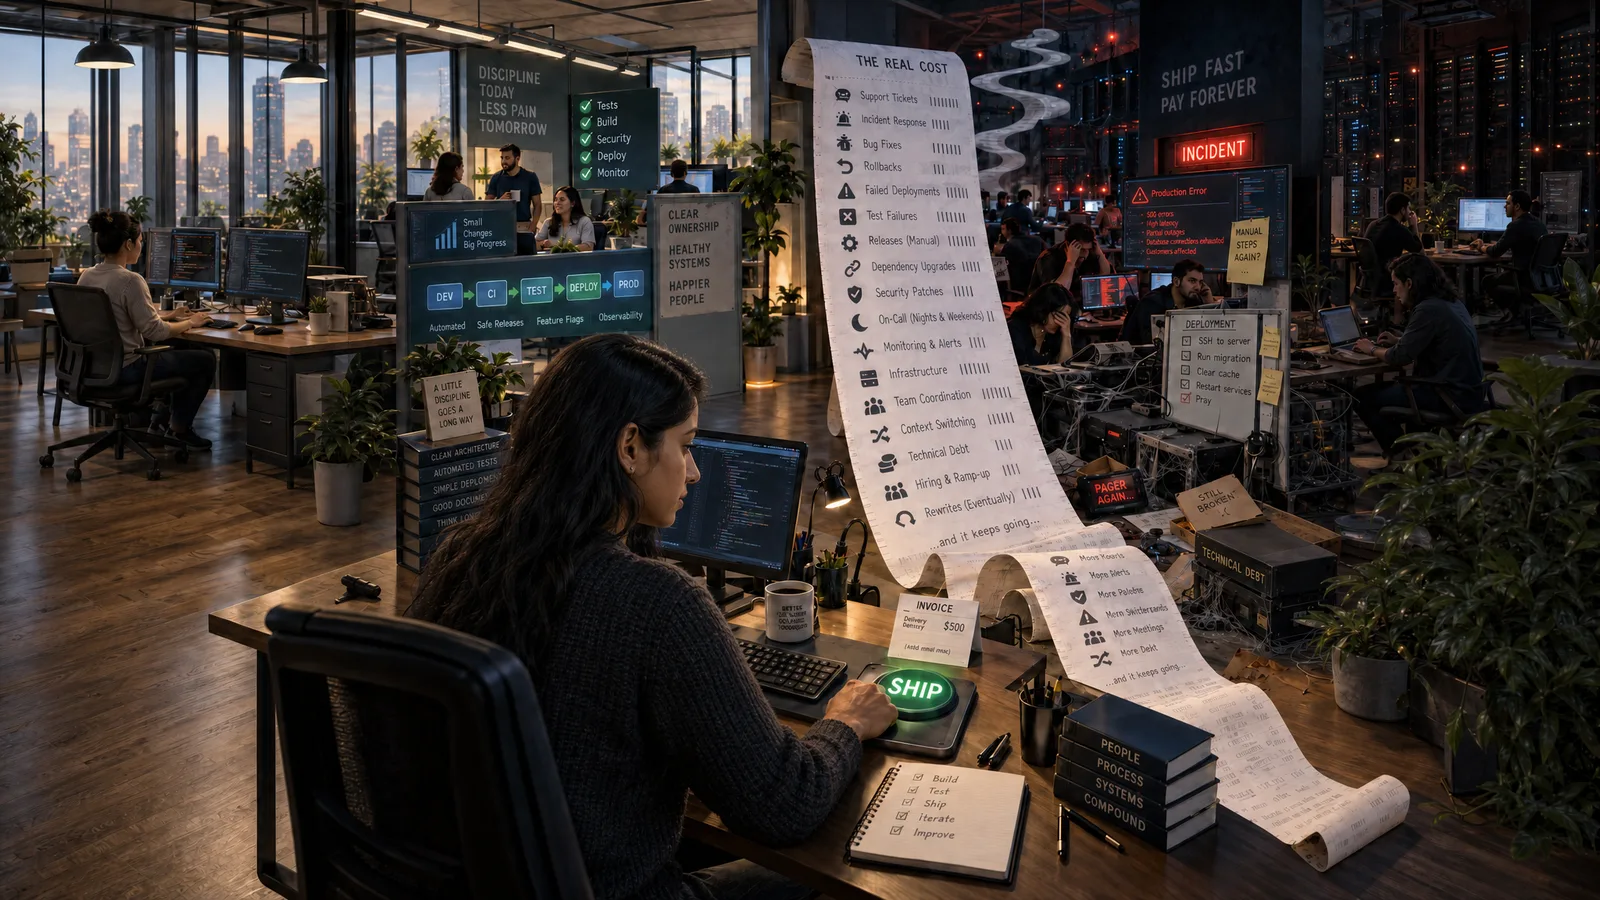
Somewhere in most codebases there is a clever abstraction that saved three days of development and has been collecting interest ever since. Software engineering has a cost curve whether we admit it or not.
Some of the cost is obvious, since salaries, cloud bills, and licenses show up in budgets and status reports where anyone can point at them. The costs that do the most damage are the ones we hide from ourselves, like the manual deployment only two people understand, the brittle test suite everyone complains about and nobody trusts, or the service that technically has an owner and still turns every incident into a scavenger hunt.
That's where cost-adjusted software engineering starts. "Did we ship?" is too small a question. The one worth asking is whether the value was worth the total cost of getting this into production and keeping it healthy, and that total includes the support burden, the customer pain, and the next team that has to open the code six months later and figure out what we were thinking.
I have seen too many teams treat delivery like the finish line. The ticket moves to done, the release goes out, and everyone moves on to the next thing, right up until production gets its say.
Shipping Fast Can Still Be Expensive
There's a version of engineering speed that looks good from far away and ugly up close. A team cuts scope, skips a little automation, and merges late. They test by hand because the automated tests are slow or unreliable, they make the deadline, and on paper the organization got exactly what it asked for.
Then the cost starts arriving. The next release is harder than it should be, and nobody is sure how to roll it back. Support tickets spike and engineers spend days explaining behavior that should have been obvious, while another team can't integrate cleanly because an interface changed and nobody told them. Someone ends up babysitting deployments, and eventually a production issue exposes the fact that nobody owned the handoff.
That speed was borrowed, and borrowed speed comes with interest.
Velocity on its own is a weak metric, because a team can move fast and still make the whole organization slower. I'm not against measuring throughput, since teams need to know whether work is moving, but raw velocity can't tell you whether the work left the system better or worse, or whether the team delivered value or just pushed the cost into next quarter.
Cost-Adjusted Engineering Is Economic Honesty
Cost-adjusted software engineering means judging engineering work by the value it creates against the full cost of creating and operating it. Making everything cheap misses the point, because cheap engineering is usually expensive engineering with a delay.
Good engineering organizations know the difference between cutting waste and starving the system. They invest in whatever makes the next change cheaper and safer, and they don't book every hour spent on automation, testing, or simplification as overhead, because those hours are what keep the cost curve from turning on them.
The ones that struggle treat every non-feature investment as optional until the pain is impossible to ignore. Then they act surprised when delivery slows down, production gets fragile, and their best engineers spend half their time holding the system together.
You Can Pay Up Front, or You Can Pay Forever
A lot of engineering leadership comes down to choosing where you want to pay. You can pay up front with better design, testing, and ownership, or you can pay later with failed releases, repeated incidents, and production fear. The second bill is worse because it compounds.
A weak deployment pipeline taxes every release, slows every fix, and makes every urgent change more dangerous. It also teaches people to avoid deploying unless they absolutely have to, so changes get bigger, deployments get riskier, and people get even more afraid to deploy, which is how a technical weakness turns into an organizational habit.
Most architecture problems are ownership problems, and unclear ownership compounds the same way a weak pipeline does. A service sits between teams, everyone knows a little about it, nobody owns it, and that works fine while things are quiet. Then something breaks, and the incident bridge fills up with people who each have part of the knowledge and none of the authority. The team that knows the code doesn't own the runtime, the team that owns the runtime doesn't know the business behavior, and the team that understands the customer impact can't make the technical change. Everyone on the call is trying to help, and nobody can move.
CI/CD Reduces the Cost of Change
People often talk about CI/CD as mainly a speed play, and that undersells it. What CI/CD does is lower the cost of change.
A good pipeline makes changes smaller and easier to validate, gives teams faster feedback, and turns rollback into a normal part of delivery instead of a last-minute panic move. It also forces the organization to care about integration before everyone has gone too far down separate paths. Code does reach production faster, but the bigger win is that getting it there takes less human attention, coordination, and recovery effort.
Long-running branches are expensive for the same reason. The merge conflict is the part everyone sees, and underneath it sit delayed feedback, hidden assumptions, and the false confidence that comes from building in isolation. A long-running branch is a bet that reality will wait for you.
Trunk-based development, short-lived branches, merge queues, feature flags, and disciplined release pipelines all exist to solve one problem: make change safer by making it smaller and more continuous. Every one of them is a form of cost control.
A deployment pipeline is an organizational contract. It says, "This is how we prove a change is safe enough to move forward," and when that contract is weak, everyone pays in a different currency. Developers pay in uncertainty and QA pays in manual effort, while operations carries the release anxiety and customers find the gaps in production.
AI Can Lower Cost, But It Can Also Increase Waste
AI belongs in this conversation because it changes the cost structure of software work. Used well, it takes friction out of a lot of engineering tasks, like generating tests, explaining unfamiliar code, and helping with a refactor. That's useful, within limits.
It can also help a team create more code than it can responsibly own. It makes complexity cheap to generate, its plausible answers still need careful review, and it will speed up the wrong work as happily as the right work. The question worth asking is whether AI improved the ratio between value created and total lifecycle cost, and "Did AI make this faster?" doesn't answer it.
If it helps a team write better tests, simplify a migration, or understand a system faster, the ratio is improving. Spraying more code into a fragile system without better ownership, validation, or operability leaves the cost problem where it was and moves the bottleneck somewhere else.
Automation in general has the same weakness, since automating bad judgment only gets you bad judgment faster.
Technical Debt Is Not the Whole Story
Engineering teams talk a lot about technical debt. The phrase is useful, but it gets fuzzy. Some debt is tolerable, some is a sensible tradeoff, and sometimes the right business decision is to accept a little mess because what you learn matters more than the polish.
The trouble starts when technical debt turns into operational risk and begins changing how the organization behaves. You see it when incident recovery depends on one person, when a simple change needs six teams to coordinate, and when customer support knows about a recurring problem before engineering leadership will admit it exists.
At that point the debt has become OpEx, and the organization pays it over and over. All code is imperfect. What leaders need to watch for is imperfection that creates recurring cost, operational fragility, or customer pain.
A messy internal tool with low change volume and a small blast radius may not matter much. A messy deployment path for a customer-facing platform matters a lot, and treating the two the same is how teams end up cleaning the wrong rooms while the kitchen is on fire.
Leaders Shape the Cost Curve
Teams usually optimize for what leaders reward. If the reward is raw speed, teams ship fast even while the system gets weaker, and a leader who celebrates output volume gets plenty of output, including the kind that creates more work than value. Heroics do the most damage of all, because a team rewarded for heroics builds systems that need heroes.
You cannot scale heroics. You can celebrate them for a while, but eventually the people carrying the system get tired, leave, or stop believing anything will change.
Cost-adjusted engineering asks leaders to raise the hard questions before the cost shows up as pain. What problem are we solving, and what is the smallest safe change? Who owns this after it ships, and how do we roll it back? What does it cost the next team, and are we fixing the class of problem or patching one symptom?
Experienced teams ask those questions so they don't have to learn everything the hard way, since the hard way usually means learning it in the middle of an incident.
Culture Is Part of the System
This is the part that makes some people uncomfortable, because cost-adjusted engineering is as much cultural as technical. I mean culture in the practical sense: what people do when there's pressure on them.
Does the team keep branches short, or does everyone disappear for weeks and integrate at the end? When a test goes flaky, either somebody fixes it or everyone learns to ignore red builds. Rollback is either something the team has practiced or a sentence in a runbook nobody has ever used.
Pressure is where weak systems show themselves. In the middle of an incident, the missing ownership, the manual steps, and the unclear decision rights all surface in the same hour, and you find out what the system around your code looks like when nobody has time to pretend.
The Practical Standard: Make the Next Change Cheaper
The practical test is simple. Did this work make the next change cheaper, safer, or clearer? If it did, the team probably improved the system, and if it didn't, the team may have delivered something while quietly raising the cost of everything that comes after it.
That doesn't mean every change has to be a platform improvement, which would be ridiculous. Sometimes a feature is just a feature, and the right move is to ship the smallest safe version and learn from it. Over time, though, the direction matters.
A healthy engineering organization bends the cost curve down by removing repeated pain, automating the things that shouldn't need judgment, and keeping deployment boring. In an unhealthy one the curve bends the other way. New features add coordination and releases add fear, and each incident produces more process without removing the cause, so the teams get busier while the system stays as fragile as it was.
That's how organizations get trapped. They're working hard and shipping, the cost of every change keeps climbing, and nobody wants to say so out loud because the dashboard still shows plenty of activity.
The Real Goal Is Sustainable Value
Cost-adjusted software engineering is about making sure the speed holds up once it meets production. Speed like that doesn't need a hero on every release, and it doesn't leave behind a support burden that grows faster than the product or push pain onto the next team and call it delivery.
The engineering organizations I'd hold up as good ones keep delivering value year after year without running up a tax on themselves, their customers, or the business, and that's what the pipeline, the automation, and the architecture are for.
Cost-adjusted software engineering is engineering with the full bill in view. Once you see the whole bill, a lot of common engineering behavior starts to look different, starting with that clever abstraction, which has been costing somebody a lot more than three days.
Frequently asked questions
What is cost-adjusted software engineering?
- It is the practice of judging engineering work by the value it creates against the full cost of building and operating it. That total includes the build and the release, the support burden, and the next team that has to maintain the system later.
Is cost-adjusted engineering just about cutting costs?
- No. The goal is to spend wisely. Cheap engineering is usually expensive engineering with a delay, and cutting waste is very different from starving the system.
Why is shipping fast not the same as being efficient?
- Speed that skips testing, automation, and ownership is borrowed, and borrowed speed comes with interest. The next release gets harder, incidents repeat, and someone ends up babysitting deployments, so a team can move fast and still make the whole organization slower.
How does CI/CD reduce cost?
- It lowers the cost of change by making changes smaller and easier to validate, with faster feedback and routine rollback. Code reaches production faster, and getting it there also takes less attention, coordination, and recovery effort.
When does technical debt actually matter?
- Technical debt matters when it becomes operational risk: incident recovery depends on one person, a simple change needs several teams to coordinate, or support knows about a recurring problem before engineering admits it. At that point the debt has become a recurring operating cost.
How do leaders influence the cost curve?
- Teams optimize for what leaders reward, so rewarding raw speed or heroics produces fragile systems that depend on heroes, and you cannot scale heroics. Leaders bend the cost curve down by asking about ownership, rollback, blast radius, and the smallest safe change before the cost shows up as pain.