"We only pay when it runs," says the team looking at the serverless bill. "This instance is cheaper if we run enough traffic through it," says the team looking at the hosted server. Both statements can be true, and both can still lead to bad decisions, which is why the cost argument around serverless is usually too shallow.
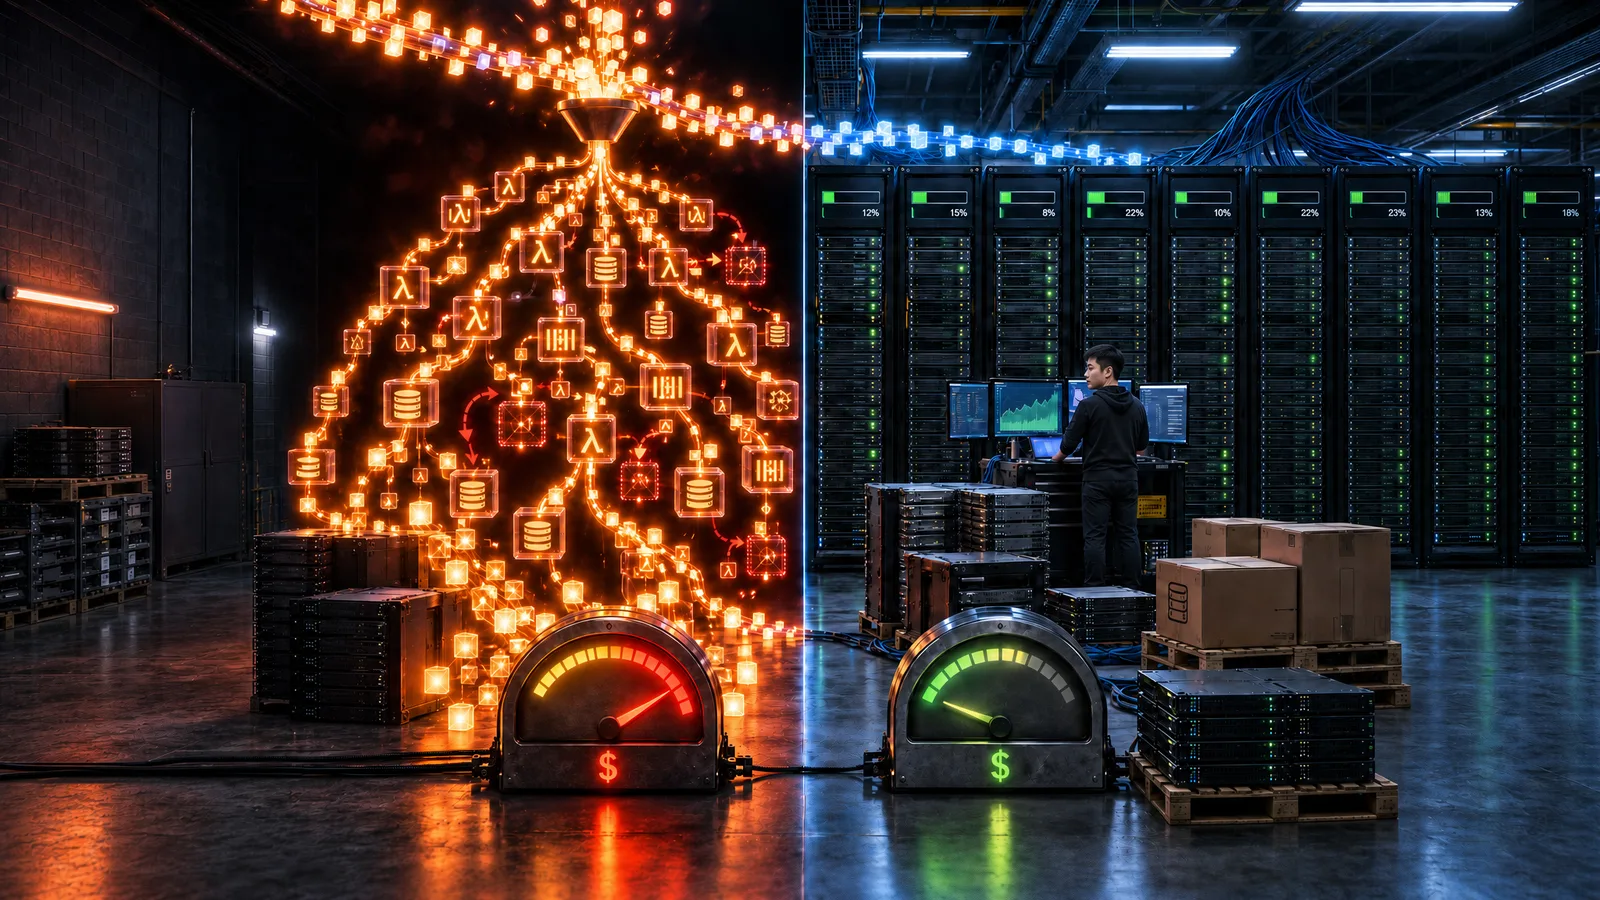
Underneath the argument is a tradeoff between utilization efficiency and economies of scale. Serverless is efficient when usage is uneven, because you pay for actual work: a request comes in, code runs, you get charged, and no request means no compute charge. Hosting is efficient when you can keep the infrastructure busy. You pay for reserved capacity whether you use it or not, and at enough sustained volume that fixed cost can beat paying a premium on every request, millisecond, or token.
Two Models, Two Kinds of Waste
Neither model is automatically cheaper. Serverless makes waste visible as usage while hosting hides waste as idle capacity, and knowing which kind of waste your workload produces tells you more than the sticker price.
With serverless, the bill follows the workload. Traffic drops overnight and the cost drops with it. For a prototype, a scheduled job, or a product whose demand nobody can predict yet, that is hard to beat, because you don't have to guess how much infrastructure to buy or build an operations model before you know whether the product matters. Nobody is paying for a server that sits mostly empty while you find out.
The Cheap Server That Isn't
I have seen plenty of systems where the cheap server wasn't cheap at all. The machine looked inexpensive on paper, but it had to be patched, backed up, and recovered when something went wrong. Somebody had to get paged for it, and somebody had to work out whether a failed deployment was the application, the host, or the ancient configuration nobody wanted to touch. That cost rarely shows up in the first spreadsheet.
A server sitting idle ninety percent of the time is expensive capacity wearing a familiar costume, however predictable the monthly bill looks.
Serverless Can Absolutely Get Expensive
Serverless gets expensive in the other direction. The pricing that makes it attractive at low utilization turns painful at high utilization, and with steady 24/7 traffic the per-request cost can add up past what reserved infrastructure would have cost. When every customer action sets off a chain of functions, queues, and third-party calls, each with its own retries, the bill grows in ways that are technically explainable and still surprising the first time someone opens it.
Serverless usually starts cheap because the early system is small, and then the architecture grows. One request becomes five functions, then fifteen. A retry policy doubles the work during a downstream outage, a chatty integration generates thousands of tiny billable events, and an AI feature that looked inexpensive as a prototype starts burning tokens in every workflow. By that point the team has scaled a cost model without ever mapping its shape.
Compare the Total Cost to Operate
Most cost comparisons ignore all of this. They set the serverless bill next to the hosting bill, the same two numbers those teams were quoting at each other, as if the vendor invoice were the whole story. What you want to compare is the cost of operating the workload safely. That includes compute, storage, and egress, and it also includes idle capacity, retries, and the people who get paged when it breaks. A hosted server that costs less on paper can cost more if it needs constant care, and a serverless system that costs more per unit can still come out cheaper if it lets the team work on the product instead of the plumbing.
Cold starts belong in that comparison too. They're a reminder that the provider is optimizing capacity across many customers, and your workload pays for that abstraction in behavior instead of idle cost. Sometimes that's fine. If you need consistently low latency, though, you can end up paying for provisioned concurrency or warmers anyway, and when you don't, the customer pays the bill in latency and errors.
Data egress is where a lot of teams get surprised. Move enough data out of a provider's network and the charge gets large whichever model you picked. It stays small enough to ignore until the product succeeds, and then it grows right along with the traffic.
Decide by Workload Shape
I like to frame the decision around workload shape. A spiky, seasonal, or experimental workload usually does better starting on serverless, because idle cost stays low and nobody has to guess at infrastructure too early. Steady, high-volume workloads, especially latency-sensitive or compute-heavy ones, can get cheaper on hosted or self-hosted infrastructure, but only if you keep utilization high and the operational complexity under control.
The break-even point isn't magic. At a simple level you compare the fixed cost of hosting against the variable cost of serverless. If the per-unit serverless cost times your expected volume comes in below the hosted cost, serverless wins, and once sustained volume pushes the variable cost past the fixed cost, hosting starts to make sense.
That math only gets you started, because it has to be adjusted for the system you actually run. How much capacity sits idle at average load once you've sized for peak? How many engineering hours does the hosted model eat, and how often does someone have to touch the infrastructure to keep it healthy? How much retry behavior and cold-start mitigation is hiding in the serverless design?
Each Model Just Moves the Waste
The wrong way to make this decision is to pick a model because it sounds modern, cheap, or familiar. The better question is which kind of waste you are willing to pay for. Serverless charges a premium for managed execution and spares you the idle capacity. Hosting can drive unit cost down at scale, and in exchange you pay for reserved capacity and operational ownership whether the system is busy or not.
Neither model eliminates waste, they just put it in different places.
Engineering teams need to be straight with themselves about that. Serverless can run up a large bill, a predictable hosting bill can hide a lot of idle capacity, and hardware that's already paid for still needs people to keep it running.
A Cost Model Is an Operating Model
For new systems I usually want the team to start with whatever buys the most learning for the least commitment. That often means serverless, managed services, or a simple hosted platform, because you shouldn't build an operations burden before the product has earned one. Mature systems with steady load deserve a second look, and the answer can go either way. Serverless may still be right because the operational simplicity is worth the premium, or dedicated infrastructure may now be justified because utilization is high and the team has the discipline to run it well, and both of those can be true of the same system at different points in its life.
Whatever you pick, pick it deliberately, because the pricing model ends up deciding how you operate. It decides where the waste goes, who owns the complexity, and whether you pay per use, in idle capacity, or during incidents. The model that fits is the one that matches the shape of the workload and the maturity of the team running it.
The cheapest system is the one that does the work reliably without making customers pay for engineering assumptions that turned out to be wrong. The two teams from the opening each had an invoice that backed up their side of the argument, and neither invoice said a word about retries, idle capacity, or who gets paged.
Frequently asked questions
Is serverless cheaper than hosting?
- Not automatically, and not as a rule. Serverless is usually cheaper when usage is uneven, low-volume, or unpredictable, because you only pay for actual work. Hosting can be cheaper at steady, high, well-understood volume, because reserved capacity spreads its fixed cost across a lot of work. Neither model is inherently cheaper; the underlying tradeoff is utilization efficiency against economies of scale.
Why can serverless get expensive?
- Because the pricing model that is attractive at low utilization can hurt at high utilization. Steady 24/7 traffic, request fan-out into many functions, aggressive retries, chatty integrations, and AI features that burn tokens all multiply the per-unit cost. At that point the team has scaled a cost model without understanding its shape.
Isn't a reserved server cheaper because the bill is predictable?
- Not necessarily. A server sitting idle most of the time is expensive capacity wearing a familiar costume, and the on-paper price ignores patching, monitoring, scaling, backups, security, and incident response. You only get economies of scale when the team can actually keep the machine busy and operate it reliably.
What should a cost comparison actually include?
- Total cost to operate the workload safely, of which the vendor invoice is only one part. That means compute, storage, data egress, monitoring, retries, over-provisioning, idle capacity, cold starts, security patching, incident response, and the engineering time to keep it all alive. A server that is cheaper on paper can be more expensive if it needs constant care.
How do I actually choose between them?
- Start from the shape of the workload. Spiky, low-volume, uncertain, or experimental workloads usually favor serverless. Steady, high-volume, latency-sensitive, or compute-heavy workloads can favor hosting, but only if you can keep utilization high and operational complexity under control. Then adjust the simple break-even math for peak capacity, idle time, retries, cold-start mitigation, egress, and recovery.
Does any model actually eliminate waste?
- No. Each model moves waste somewhere else. Serverless trades idle cost for a premium on managed execution; hosting trades that premium for reserved capacity and operational ownership whether the system is busy or not. The useful question is which kind of waste you are willing to pay for.