Talk to Dave. Only Sarah knows that pipeline. Use Jenkins, but not that Jenkins. Never on Fridays. Those are all answers to one of the fastest diagnostics in software: can I deploy your code, right now, safely, using the process the team claims to trust? A clean answer means deployment is a repeatable process. An answer that routes through Dave means you've found a fragile system protected by institutional knowledge, where every deployment that needs a specific human is technical debt the organization has learned to call expertise.
The blog as of 754f461
A cumulative snapshot of every article published up to Context Switching Is a Lie on June 26, 2026. 13 articles. View the current list →
An engineer is deep in a problem, someone taps them on the shoulder, and productivity falls off a cliff. Every part of that story is true, and it still blames the wrong thing. The interruption only hurts because software delivery runs on fragile human memory, with the engineer as the one place the working model of the change lives. AI raises the stakes by turning individual contributors into managers of small AI teams. The fix is to write the context down where it survives a sick day, a handoff, or an AI session ending.
Turn the lights off in a factory and, in a few famous plants, nothing stops. Now turn the lights off on your software delivery for one release: nobody translating tickets, nursing pipelines, or watching dashboards. How far would a change get? For most teams a fully autonomous delivery system is impractical, which is exactly what makes it a useful forcing function. Wherever the workflow breaks first is where your delivery still depends on tribal knowledge, unclear ownership, or a rollback plan nobody has practiced.
CI/CD may be the only acronym in software that teams adopt backwards. Teams that say they want CI/CD usually just want the deploy button to hurt less, so they reach for CD first. The first problem is CI, which comes down to trunk-based development and automation added to all new work. Get those right and CD becomes a controlled move of a known-good main branch instead of a faster way to ship uncertainty.
A five-line change should not take five days to ship, but chase a small fix across four repositories and that is what happens: the code is the fast part, and the coordination burns the week. Arguments about monorepos usually start with tooling when the question underneath is coordination, because a repository structure is a delivery model that encodes ownership, release flow, and how much coordination people need before they can safely ship. Size repositories around deployables and publishables so the repo boundary tells the truth about how the software ships.
A developer leaves standup with a ticket and comes back the same day with an implementation, a migration plan, and three pull requests; a year ago that was a week of work. AI made execution dramatically faster, but most teams are held back by planning and validation, and AI does little for either by default. Speed up only the middle of the delivery system and the work backs up at review, testing, and deployment. The fix is to improve the whole loop, starting with the two stages AI left alone.
We only pay when it runs, says one team; this instance is cheaper at volume, says the other. Both can be true, and both can lead to bad decisions. Underneath is a tradeoff between utilization efficiency and economies of scale: serverless makes waste visible as usage, and hosting hides it as idle capacity. The cheapest system is the one whose cost model matches the shape of the workload and the maturity of the team operating it.
Production is broken, engineers are on a call, and every few minutes a voice says "we think we're close." Everyone is busy, nobody is lazy, and the customer is still broken. Once a defect is in production, the customer should not become part of your debugging environment. Triage that feels like progress (more logs, another build) often means the customer keeps absorbing the failure while engineering looks for certainty. Stop the bleeding first, then diagnose.
'I am the only one who knows how to do this' sounds like a flex, but most of the time it means part of the system only works because you are standing next to it. Working yourself out of a job means removing the broken, fragile, one-person-dependent parts of your work so the system no longer needs babysitting. The engineers worth keeping make their hardest problems boring, hand them off, and earn their way into bigger ones.
The demo worked, the team hit the date, and everyone felt good for about thirty minutes. Then the support tickets started. Boring software can be as clever as you like to build. The part that should be boring is running it in production, with practiced rollbacks, clear ownership, and nobody relying on heroics to get through the week.
I started writing software before source control was a given, back when you found out who changed a file by asking around. Git made creating branches cheap, but it never made integrating them cheap. Long-running branches feel productive to the developer who opens them, while the cost lands on everyone else as delayed integration and uncertainty that surfaces right before a release. Trunk-based development is where you end up once you take CI/CD seriously.
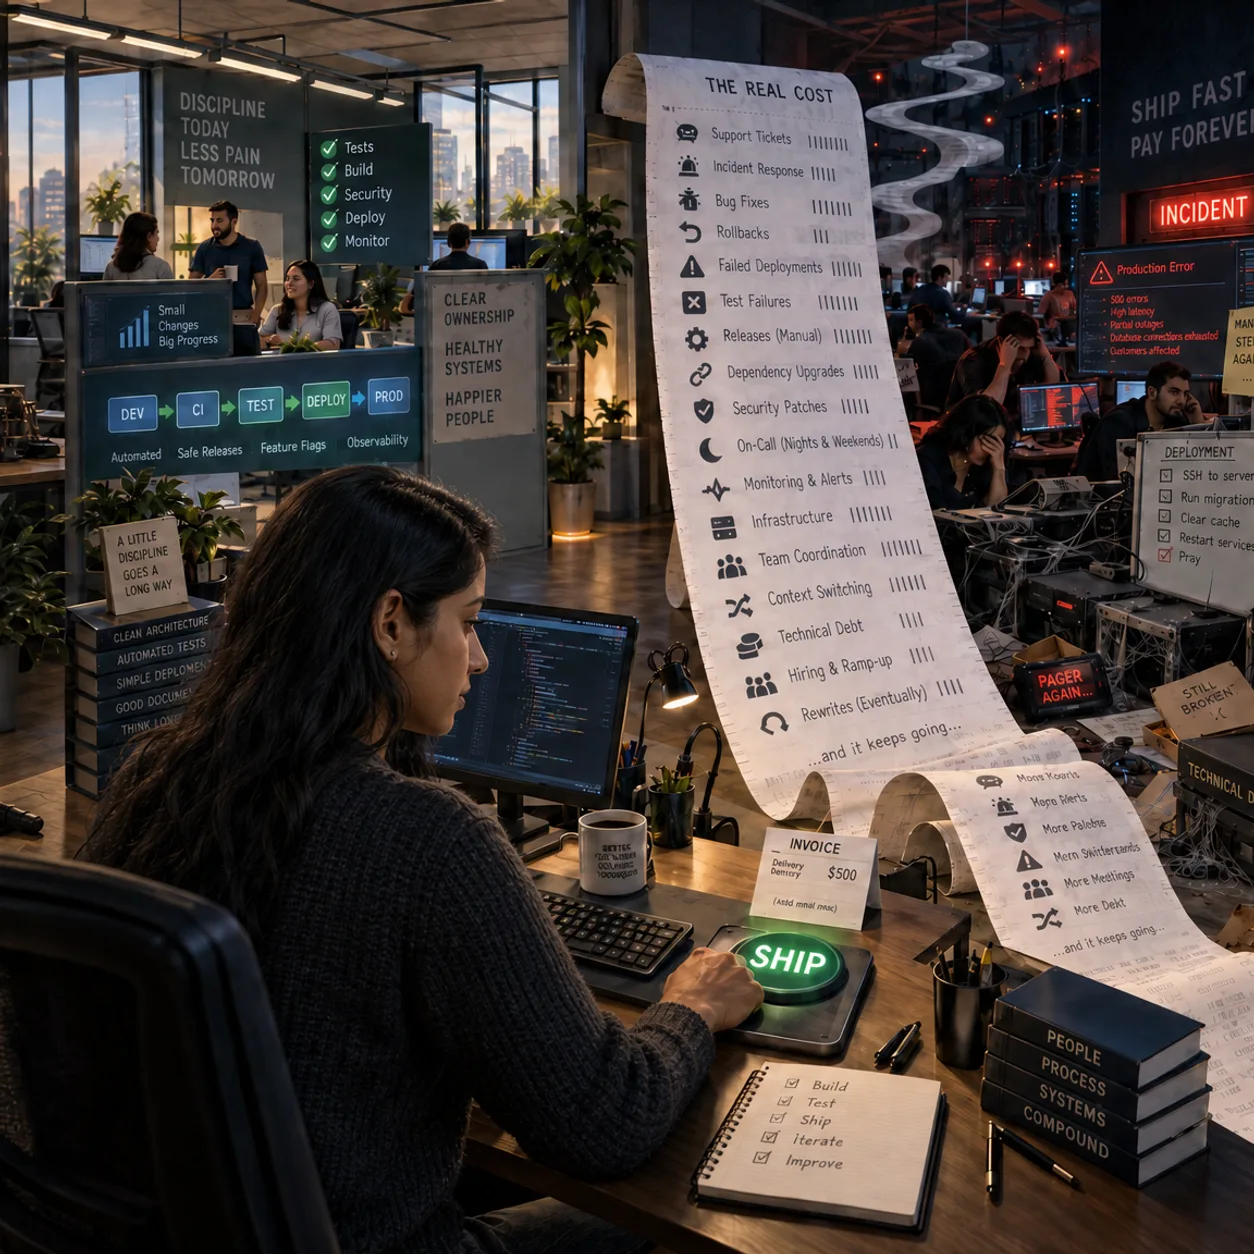
Somewhere in most codebases there is a clever abstraction that saved three days of development and has been collecting interest ever since. Cost-adjusted software engineering judges work by the value it creates against the full cost of building and operating it. You can pay up front through testing, CI/CD, and clear ownership, or pay forever through incidents and rework.
Every software system exists twice: once as what the team believes it built, and once as what shows up after it ships. This blog lives in the gap between the two, writing about ownership, deployment, operations, and the people underneath, starting from the idea that most architecture problems are ownership problems.